XYZT builds inference accelerators for edge AI and large language models—hardware
that runs useful models locally, within tight power and memory budgets, without
relying on datacenter-scale machines. The aim is to make capable AI inference
accessible where latency, privacy, and cost matter: on device, at the edge, and
outside the cloud.
Computer design has plateaued. The industry mostly adds transistors and cores, or
rearranges existing blocks. The binding constraints are memory bandwidth and
interconnect bandwidth—not peak arithmetic throughput. Optics may help at board or
rack scale; the hard problem is on-chip SRAM and on-package DRAM bandwidth.
LLM inference exposes this gap directly. Over the past twenty years, compute
throughput on server-class AI hardware has outrun DRAM and interconnect bandwidth
by orders of magnitude. Prefill can be compute-heavy; decode at small batch
streams weights through memory with very little reuse. Weights and the key-value
cache must fit on chip. The goal is to use on-package bandwidth efficiently in
that decode regime—not to chase peak FLOPs that sit idle.
At the edge the limits are tighter still: a DRAM access costs orders of magnitude
more energy than a useful arithmetic operation, and when reuse is low, power goes
to data movement. In a systolic array, compute grows with the square of its size
but off-chip I/O grows only with its edge. Our lever is local reuse and
nearest-neighbour dataflow—arrays sized to what on-package memory can actually
feed, for LLM and edge inference workloads that need throughput per watt, not
headline peaks.
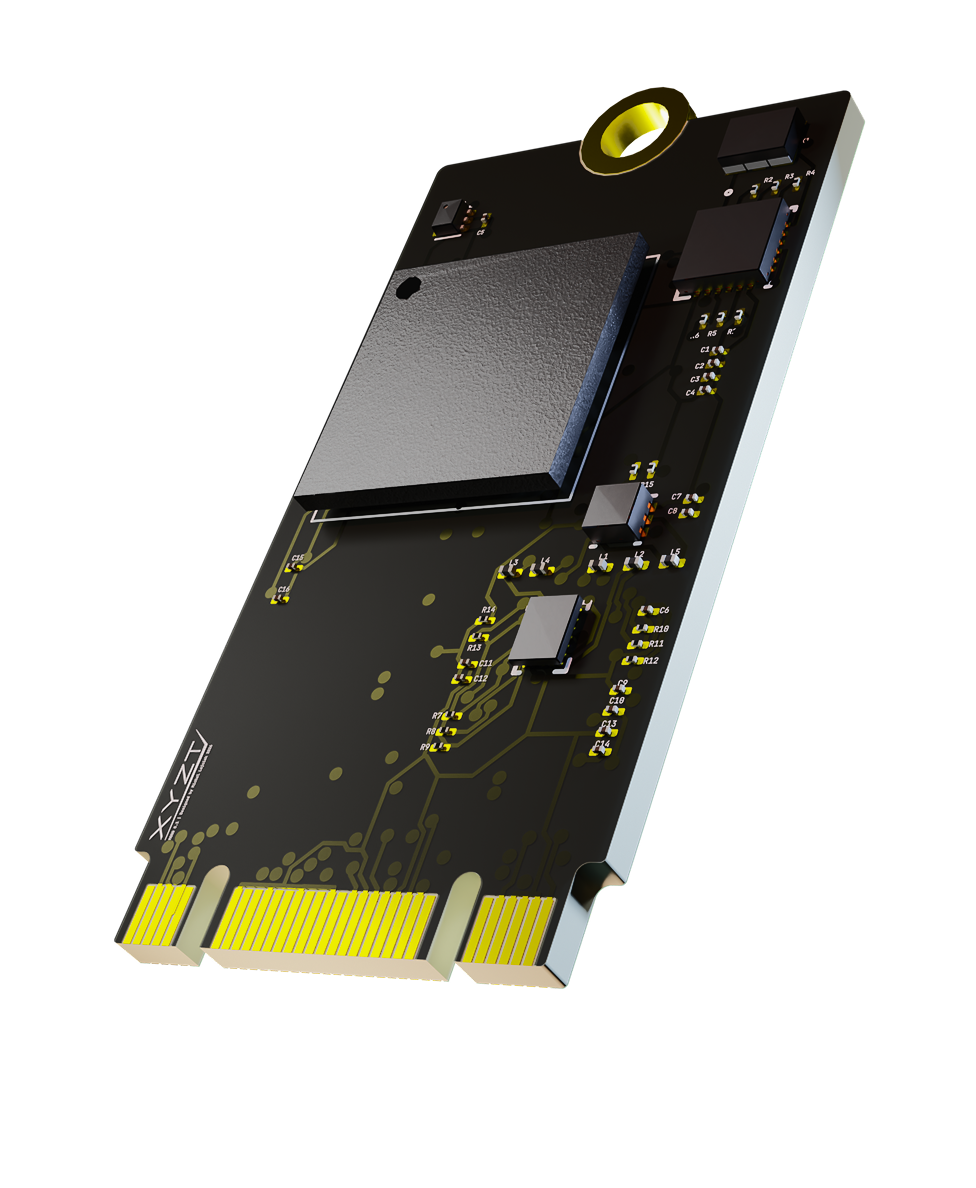 Coming in 2026